
Enterprise AI, in production.
    Four desks, one beat.

    BankingOpinion

    Leaders Opinion: Navigating Overconfidence Challenges in Large Language Models (LLMs)

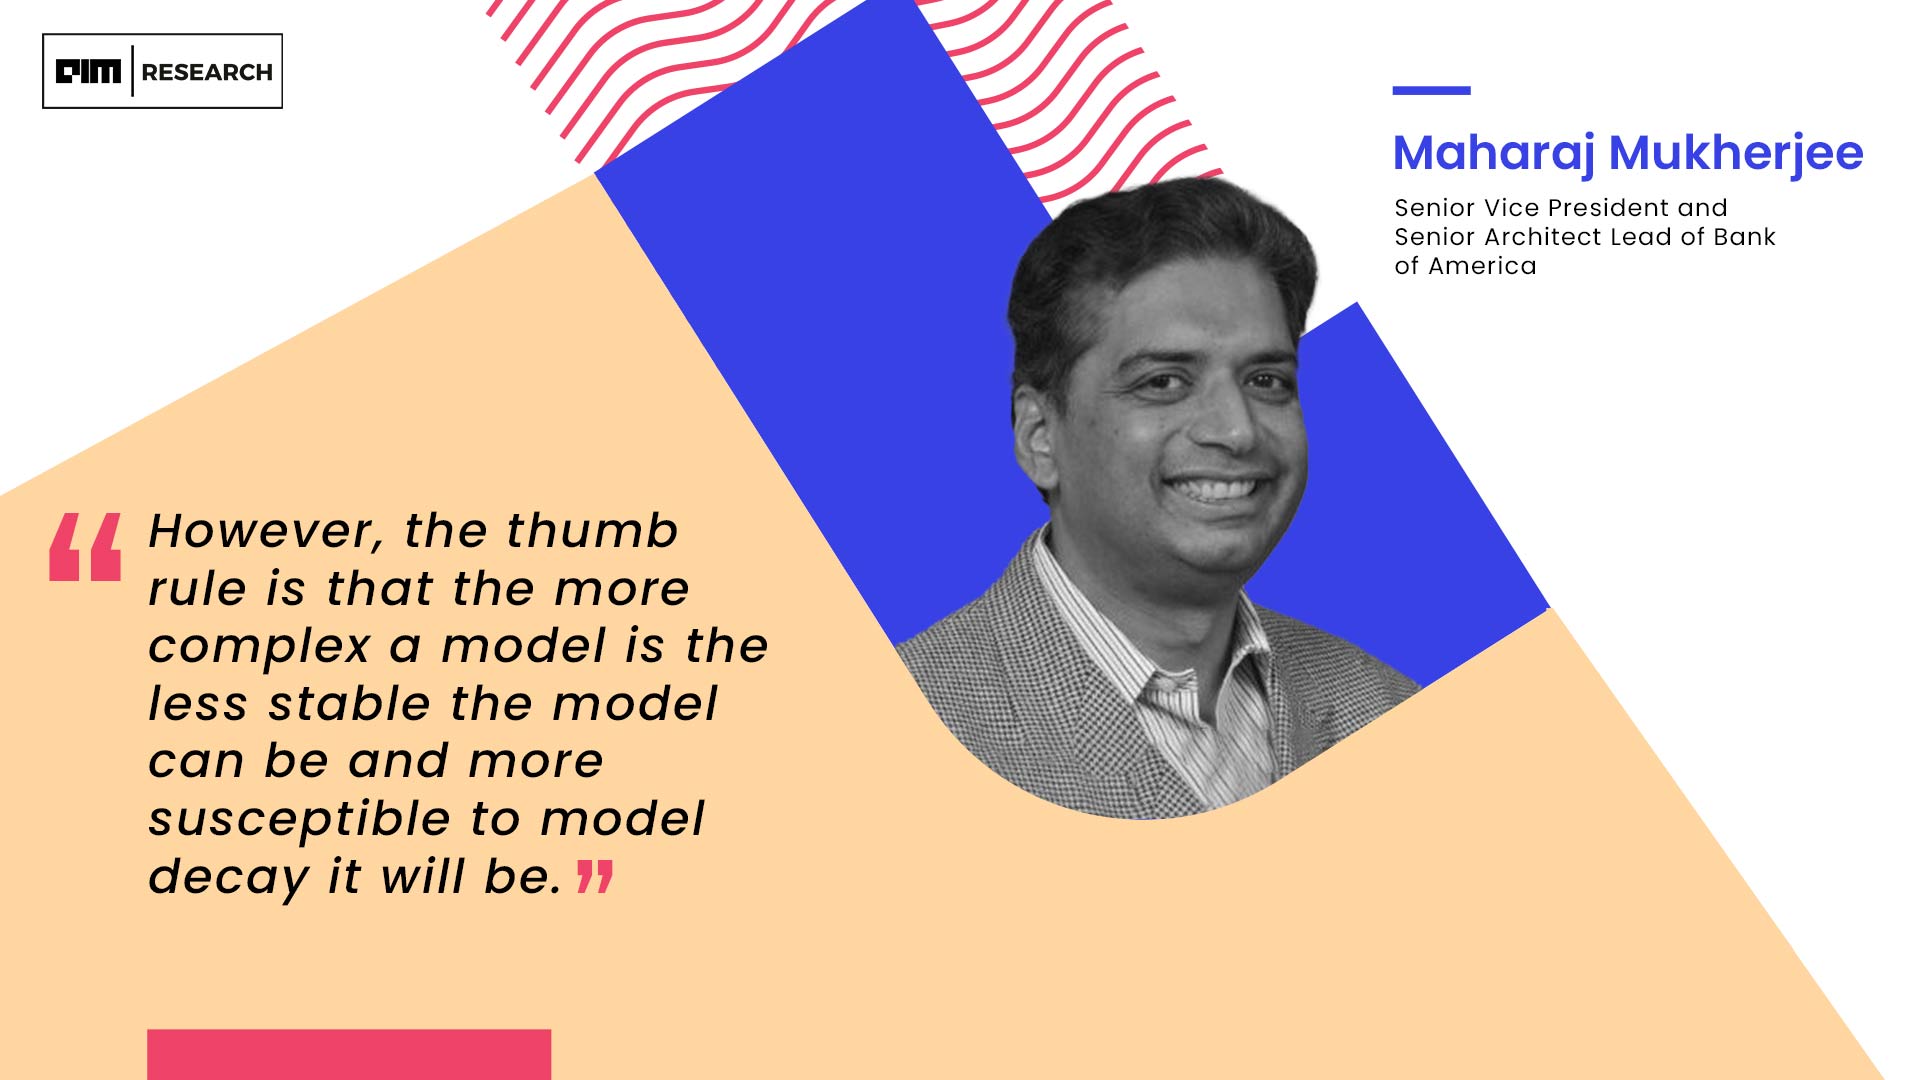
    However, the thumb rule is that the more complex a model is, the less stable the model can be and more susceptible to model decay it will be. It is expected that LLM models because of their inherent complexity would decay quicker.

    Last updated

    Leaders Opinion: Navigating Overconfidence Challenges in Large Language Models (LLMs)

    Developers fine-tuning Language Model (LLM) models often face a challenge known as overconfidence. In an experiment by Jonathan Whitaker and Jeremy Howard of fast.ai, this issue was explored, shedding light on the less-discussed problem of overconfidence in LLMs. Overconfidence occurs when the model asserts incorrect information from the dataset, potentially due to underfitting and overfitting, which represent the balance in the bias-variance tradeoff.

    Maharaj Mukherjee, Senior Vice President and Senior Architect Lead of Bank of America weighed in on the matter, “One thing that is almost certain for any ML model is the model decay. The model will sooner or later provide erroneous or erratic results with deteriorating value and predictability. Complex systems that depend on multiple models are impacted more by model decay. The model with the shortest half-life impacts the value and predictability of a multi-model system. The model decay can be due to many different reasons. The more common reason is the data drift that can happen when the data changes because of unforeseen reasons.”

    Overfitting occurs when a model becomes too tailored to the training data, while underfitting happens when the model lacks sufficient data for accurate predictions. To address these issues, developers employ various techniques, with mixed success.

    Additionally he said that, “Usually, the data drifts are slow and can be verified and corrected in the model by keeping close watch on the model quality. Oftentimes, collecting additional data and minor recalibrations may correct for the data drift. However, correcting for concept drift or hypothesis drift, the other reason for model failure or decay, is extremely difficult. In any case, after some time, it makes more sense to rebuild a new model. Rebuilding a new ML model requires a lot of data scientist efforts and costs both time and money.”

    by AIM Media HouseFree · No paywall

    Keep reading. It's free.

    Create a free Deployed account to finish this story and every story on the site. Choose the briefings you want with it:

    or

    No credit card. One click to unsubscribe. Already a reader? Sign in

    About the author

    Deployed

    Related stories