
 Banking
Data is the foundation of AI, but the majority of it is in formats that are unsuitable for modelling. Unstructured data, which ranges from financial documents buried in PDFs to contract terms spread across spreadsheets, is a constant bottleneck for businesses looking to build AI-powered solutions. While traditional OCR and AI-based parsing tools have been around for decades, they often fall apart when faced with complex formatting, domain-specific jargon, or intricate tables.
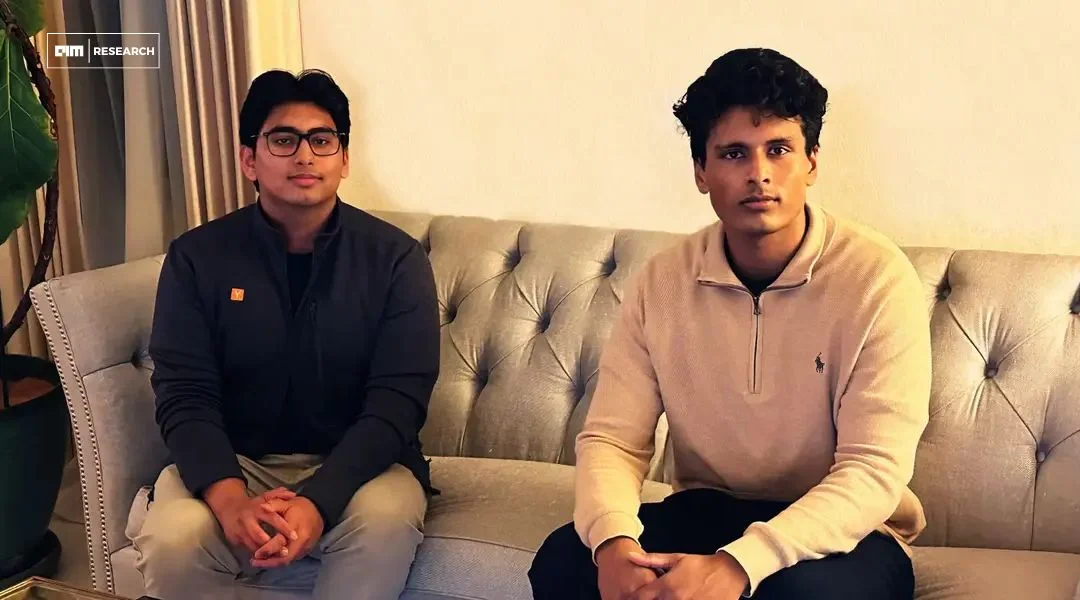
Pulse, a San Francisco-based firm, argues that the current technique to document understanding is fundamentally flawed. Pulse, founded last year by Sid Manchkanti and Ritvik Pandey, has built an API for extracting LLM-ready data from documents while assuring correctness and structure at scale. Nat Friedman and Daniel Gross (NFDG) led the $3.9 million seed round, which also included Y Combinator, Sequoia Capital Scout, Soma Capital, Liquid 2 Ventures, Olive Tree Capital, Tiferes, and executives from NVIDIA, OpenAI, and Ramp.
The funding will allow Pulse to expand its engineering team and extend its extraction capabilities beyond text-based documents to include audio and video, enhancing data ingestion pipelines for enterprises.
