
 Pharma
As AI companies scramble to build ever more capable models, data labeling has gotten its moment in the spotlight. Ex. the Meta-Scale AI deal, which saw Meta take a 49% stake in Scale and hire its CEO, injected new energy and scrutiny. With foundational models shifting from static, pre-trained systems to continually evolving, reinforcement-tuned AI agents, the role of high-quality, domain-specific data is more important than ever.
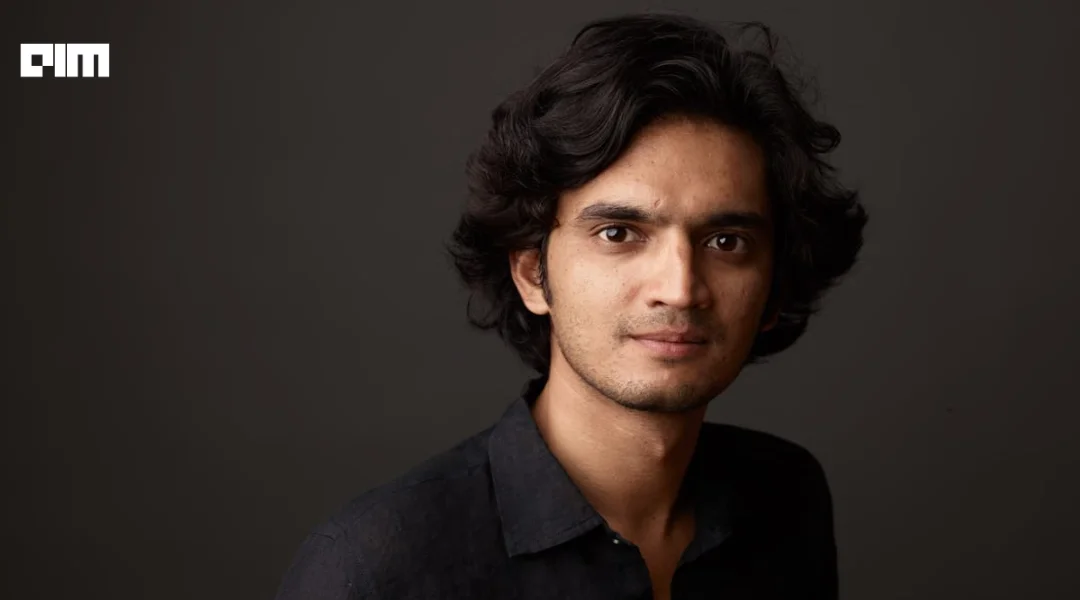
Labelbox wants to lead this shift, even as advances in synthetic training models raise existential questions about the future of human-in-the-loop data labeling. Co-founder and CEO Manu Sharma appeared on a16z’s podcast to talk about what he sees as their opportunities.
AI Created an Inflection Point
Over time, as transformers and generative models took center stage, the company, which began in 2018, faced an inflection point. Supervised learning had plateaued in its ability to power increasingly complex tasks. In response, Labelbox expanded its platform from vision to text and audio, and from tools to services. But it wasn’t until the rise of reinforcement learning and human preference modeling, post-training techniques like RLHF and SFT, that the company made its biggest leap.
