
 Manufacturing
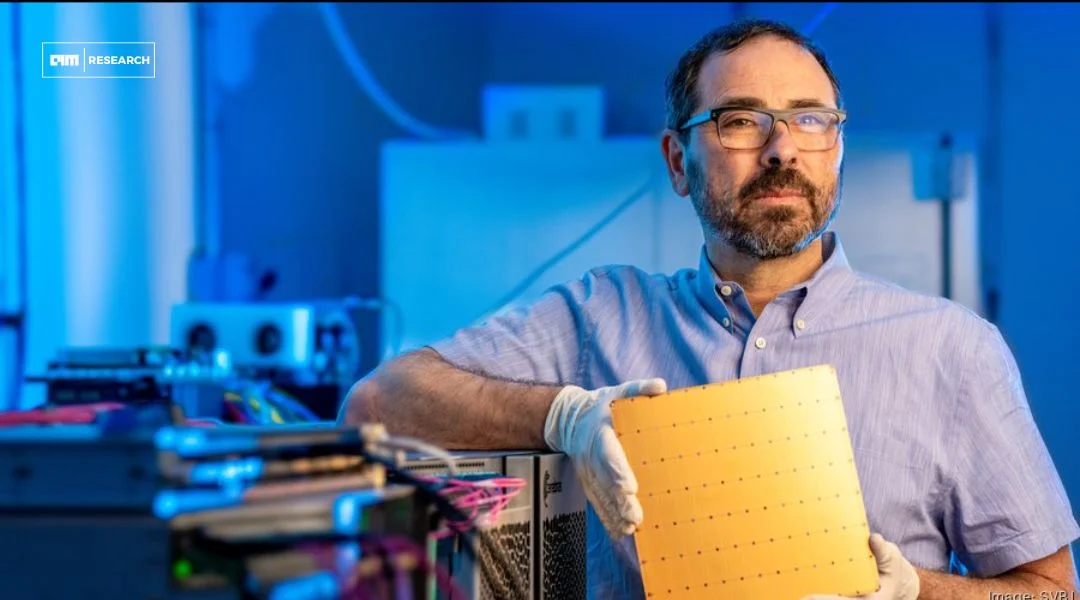
AI hardware is at an inflection point, and Andrew Feldman sees the shift with absolute clarity. The founder and CEO of Cerebras Systems has long argued that AI’s demand for compute power cannot be met by conventional GPU-based architectures. As models grow larger and more complex, the industry must move beyond the constraints of traditional chips. His answer? Wafer-scale computing.
GPU's Are Not Built For AI
For years, Nvidia has dominated AI hardware with its GPU-based ecosystem, which thrives on parallel computing. But GPUs were never built for AI; they were adapted for it. The more AI scales, the clearer the inefficiencies become. Moving data on and off the chip—one of the most power-intensive operations in AI processing which creates bottlenecks that hamper both efficiency and performance.
The standard workaround has been to use clusters of GPUs, connected through high-speed interconnects, to distribute the workload. But this approach is increasingly hitting its limits. Interconnect overhead increases latency, consumes excessive power, and forces engineers into a constant game of optimization to compensate for hardware inefficiencies. Even with advancements like Nvidia’s NVLink and other interconnect solutions, the underlying issue remains: distributing a workload across multiple discrete chips introduces unavoidable inefficiencies that scale poorly as models grow larger.
