
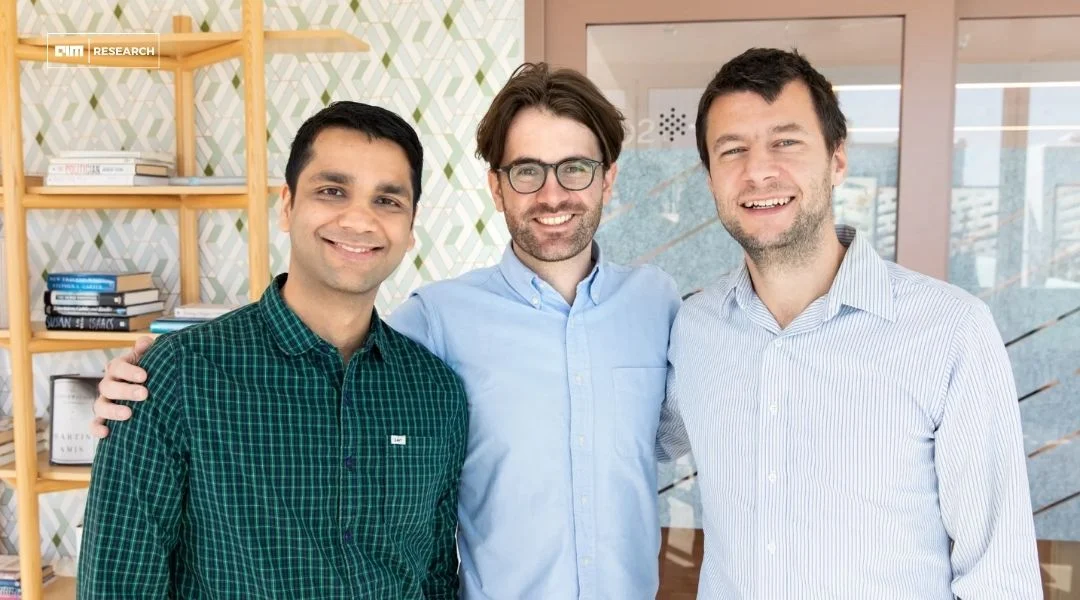
For years, large language models (LLMs) have operated within a well-defined paradigm: autoregression. Each word or token is generated sequentially, one at a time, creating a fundamental bottleneck in speed and efficiency. This has led to increasing inference costs and latency issues as AI-generated text becomes more complex. Now, Inception Labs, a startup co-founded by Stanford professor Stefano Ermon and his colleagues Volodymyr Kuleshov and Aditya Grover, is introducing a different approach, diffusion large language models (dLLMs). Their first commercial-scale product, Mercury, aims to disrupt the status quo by offering significantly faster and more efficient text generation.
The Diffusion Model Shift
Traditional LLMs, including OpenAI’s GPT-4o and Anthropic’s Claude 3.5 Haiku, generate text in a left-to-right fashion, with each token dependent on those before it. While this sequential process allows for contextual depth, it also means that longer responses come with exponentially increasing computational costs. Companies optimizing these models have focused on test-time computation to improve reasoning, but this approach has created trade-offs in speed and usability.
Diffusion models, by contrast, operate differently. Rather than generating one token at a time, they use a “coarse-to-fine” approach, refining an initial rough estimate in parallel over a series of denoising steps. This method is widely used in AI-generated images, video, and audio—powering tools like OpenAI’s Sora, Midjourney, and Riffusion—but its application to text has been largely unsuccessful. Until now.
